Best Momentic Alternatives in 2026: Who Still Writes the Tests
Momentic now reads PR diffs and tests native mobile, so the old gaps closed. We compare six alternatives on the question still standing, who writes the tests.
Most “best Momentic alternatives” lists get the assignment wrong. They line up ten AI testing tools that all do the same thing Momentic does, drop a feature grid on top, and call it a comparison. Pick that way and you end up paying for a second version of what you already have.
Here is what those lists skip. Momentic is good, and it got better in June 2026. It raised a $15M Series A led by Standard Capital in November 2025, teams at Notion, Quora, and Webflow use it, and a platform release that summer added native mobile and an agent that reads your pull-request diffs and proposes tests for what changed. Half the reasons the older comparison posts give you for leaving Momentic stopped being true that day.
What did not change is who ends up holding the suite. An agent can propose a test, but someone on your team reviews it, merges it, and owns it the next time it breaks. The six tools below separate on that question.
What you’ll learn
- What Momentic does well, and the three constraints that send teams looking elsewhere
- Six real alternatives with ratings, pricing, and real pros and cons
- How a tool, a managed service, and an autonomous platform differ in what your team owns
- A decision framework that maps your constraint to the right alternative
Why Teams Look Past Momentic
None of the reasons below is “Momentic is bad.” Momentic is an AI end-to-end platform where engineers describe tests in plain English, Momentic stores them as human-readable specs in the repo, they run in CI, and the specs self-heal when the UI shifts. It was founded in 2023, went through Y Combinator’s Winter 2024 batch, and has since shipped hosted iOS and Android devices plus a diff-reading agent. Serious product, and a moving target. The reasons to look elsewhere are about fit.
Two complaints these lists keep leading with are out of date, so cross them off first. Momentic does test native mobile, on hosted emulators, billed by the device minute. And coverage no longer waits on a human to notice a gap, because the agent proposes tests off the diff when a pull request lands. What survives is narrower and harder to fix.
- Mobile is priced as a meter, not a surface: The pricing page bills hosted devices at 8 credits a minute on Android and 15 on iOS, and the $125 tier caps you at five concurrent devices of each with fifteen-minute sessions. Fine for a smoke suite, awkward for a mobile-first product whose entire regression pass is mobile, because the meter runs hardest against the thing you most need to test.
- Who writes the tests: The workflow assumes engineers. A proposed test is a draft someone has to read, and a QA org staffed with manual testers and no automation engineers hits friction right there. testRigor or a managed service fit that org better.
- Ownership: Even with self-healing and a diff-reading agent, the suite is yours, along with the triage and the coverage decisions. Some teams do not want to own a test suite at all. They want coverage to arrive as a result, which is the line between an authoring tool and a managed or autonomous platform.
- The diff is not the app: Reading a pull request tells a tool what changed in the code. It does not tell it what the change did to the screen three flows away, and that second-order break is the one that reaches a user.
Tools (Momentic, testRigor, mabl, Playwright) make authoring faster and leave the suite with your team. A managed service (QA Wolf) or an autonomous platform (Pie) makes coverage itself the deliverable. Compare on what your team owns afterward.
Quick Answer: Six Best Momentic Alternatives
The six strongest Momentic alternatives in 2026 are Pie, QA Wolf, testRigor, mabl, Applitools, and Playwright. They solve different problems. Pie removes authoring by discovering the app and generating the suite, QA Wolf takes over the entire suite as a managed human service, testRigor and mabl are authoring tools your team keeps owning, Applitools covers visual regression specifically, and Playwright is the free, code-based option. The table below maps each to the constraint it solves.
| Tool | Category | Best for | Native mobile | How tests are made | Who owns the suite |
|---|---|---|---|---|---|
| Momentic | AI authoring tool (web-first) | Engineers writing plain-English E2E in CI | iOS + Android (hosted, metered per minute) | Authored in plain English; an agent proposes from PR diffs | Your team |
| Pie | Autonomous QA platform | Native mobile coverage with no test authoring | iOS + Android (simulators/emulators) | Autonomous discovery (nothing authored) | Pie generates and maintains |
| QA Wolf | Managed service (humans + AI) | Outsourcing QA entirely | iOS + Android (real-device iOS) | Authored by QA Wolf’s engineers | QA Wolf’s team |
| testRigor | Plain-English authoring tool | Non-technical QA teams, no engineers | iOS + Android (plus Windows desktop) | Human-authored plain English | Your team |
| mabl | Low-code unified platform | Enterprise low-code with governance | iOS + Android (simulators/emulators) | Low-code, AI-drafted from prompts | Your team |
| Applitools | Visual AI (Eyes) + codeless E2E | Deep visual regression on any framework | Web + mobile (via SDKs) | Layered onto tests you already have | Your team |
| Playwright | Open-source framework | Engineers wanting control and zero spend | Web + mobile-web emulation only | Hand-coded by your engineers | Your team |
Every tool here claims AI, self-healing and natural language, so those words separate nothing. We applied five criteria the same way to every row.
- Ownership model: Tool, managed service, or autonomous platform, which decides whether your engineers spend their week maintaining tests.
- How the tests get made: Authored by a person, derived from your code and pull-request diffs, or discovered from the running app.
- What a test is checked against: The implementation, or the behavior a user sees.
- Native mobile depth: Whether iOS and Android are the core loop or a metered add-on.
- How it is priced: A number you can read before you talk to anyone, or a conversation with sales.
Ratings were read in September 2026 off G2, Capterra and Gartner Peer Insights, and they move week to week, so treat them as directional and check the review count next to the score. We build Pie, and Pie is first on this list because we wrote the list. Read our row the way you would read any vendor grading its own homework, and hold it to the claims a twenty-minute trial could disprove. Where a rival does something better than we do, it is said plainly below, because a comparison that never concedes anything is an advertisement.
The most expensive evaluation mistake we watch teams make is comparing on features instead of ownership. A tool that drafts tests twice as fast and then hands you the suite to maintain has only moved the cost. In the Capgemini WQR 2025-26, 50% of organizations cite maintenance burden and flaky scripts as a test-automation challenge. Where that maintenance lands, on your team or on the tool, is the question a demo never answers.
Six Momentic Alternatives Worth Checking Out
The six are ordered by how much of the suite leaves your team. The first two hand it over completely, one to software and one to people. The middle three make authoring easier and leave you holding it. The last one hands you the code and the bill for keeping it working.
1. Pie: Autonomous Coverage, Native-Mobile-First
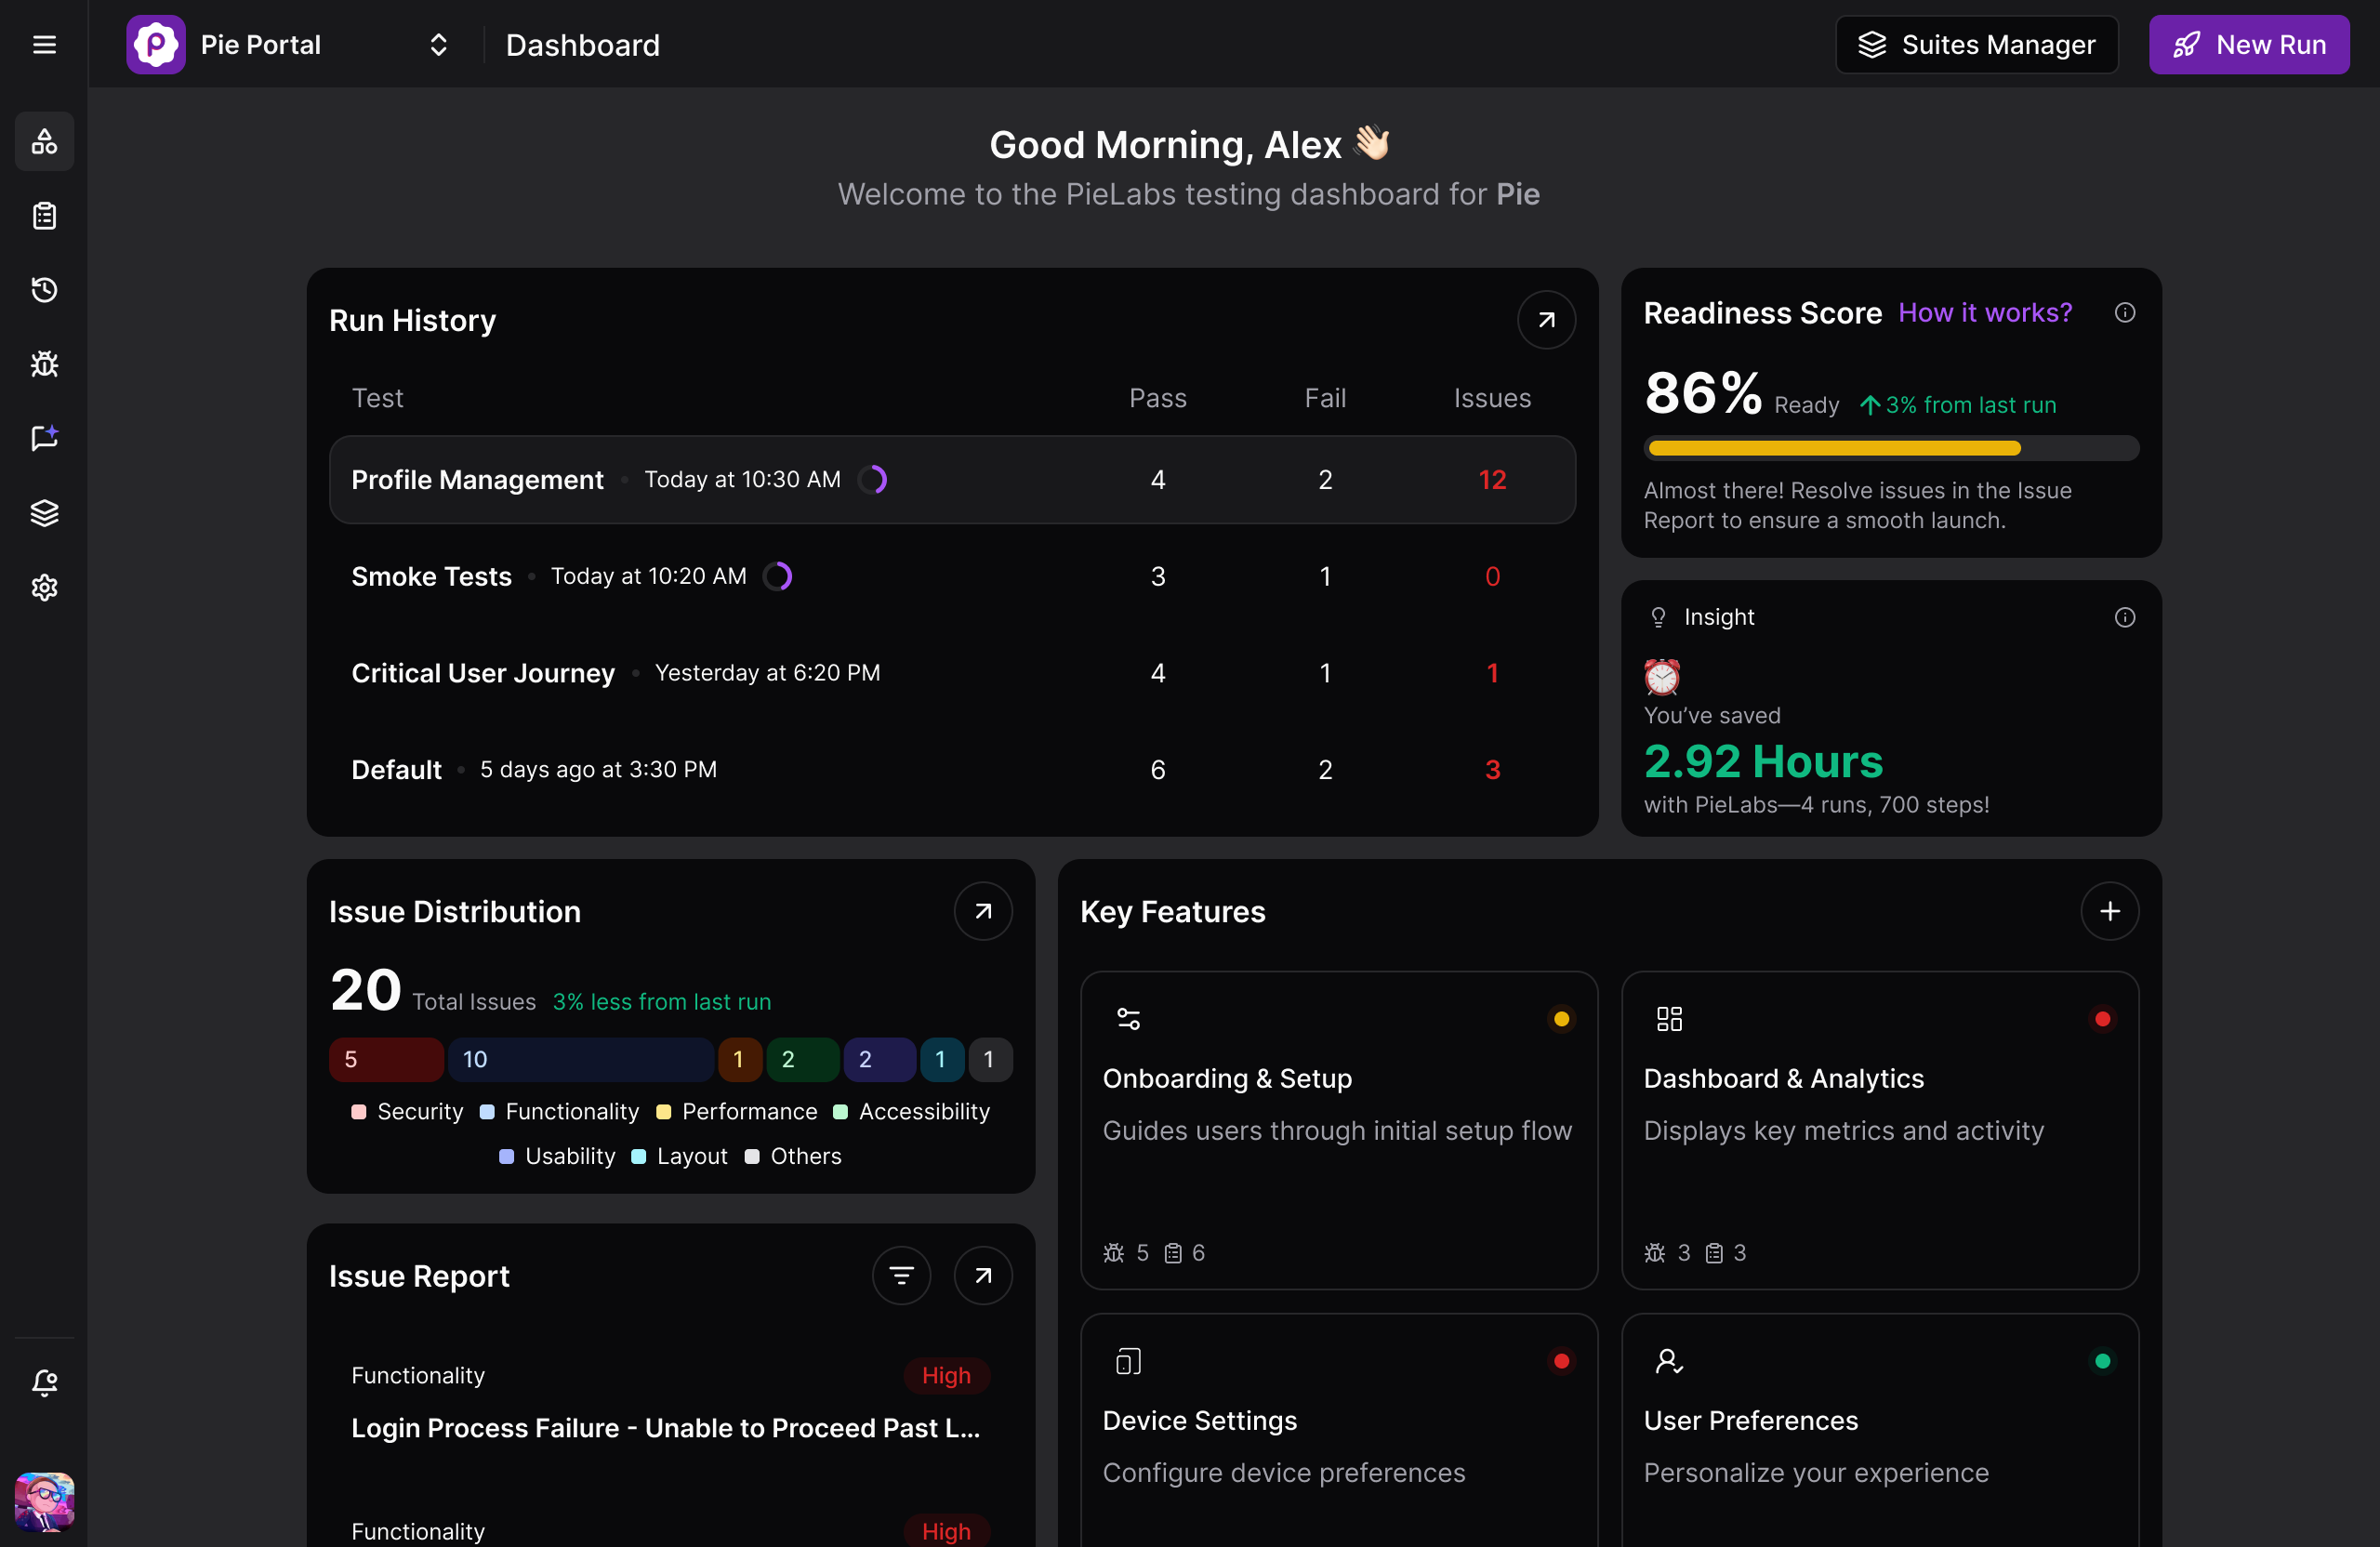
Pie is an autonomous QA platform that tests your app the way a person does, by looking at the screen. Instead of asking an engineer to author flows, Pie ingests your app, explores it on its own, maps the user flows, and generates the test coverage. On native mobile it reads the rendered UI from screenshots with a vision model rather than parsing selectors or the accessibility tree, so a redesign does not break the tests and coverage self-heals as the app changes.
Mobile reach no longer separates the two, since both cover it. The split is who owns the result. Momentic proposes a test for an engineer to approve and keep, while Pie treats discovery, generation, runs and maintenance as the platform’s job, so no one on your side reviews a draft or inherits it. Pie also closes the loop past detection. When a test catches a regression, Pie Loop drafts the fix as a reviewable pull request for an engineer to merge instead of stopping at a red build.
Rating (September 2026): 5/5 on Gartner Peer Insights, from three reviews.
What makes the difference in practice:
- Autonomous discovery maps real user flows and generates coverage with no test authored by hand
- Vision-based mobile execution identifies elements by what the user sees, so redesigns and OS updates do not break the test
- One behavior-based definition runs across web, native iOS, and native Android
- Findings are verified before they reach you, so flaky noise is filtered out and only real issues surface
- Pie Loop turns a caught regression into a drafted pull request, not just a failing run
Honest trade-offs:
- Not a raw grid you point a legacy Selenium suite at, and not built for unit, load, or API testing
- Pie runs on simulators and emulators, so hardware-specific behavior is out of scope
- Smaller ecosystem than decade-old projects, as with any newer platform
Autonomous discovery cuts both ways. It is a strength when you want coverage without asking for it and a limitation when you need one exact flow tested by Thursday, because you are asking a system that decides what matters to prioritize what you care about. Momentic’s model is better at that, and so is any tool where a person writes the case. Pie takes plain-English test cases for exactly this reason, but if your team’s complaint about testing is “I want to write ten specific assertions and run them,” you are describing an authoring tool, and you should buy one.
Fi, the AI-powered GPS pet collar company, cut release validation from two to three days down to a few hours and shrank testing from 12+ engineers to one dedicated QA after moving to autonomous coverage.
Pricing: Platform subscription, shaped to your app and the surfaces you want covered. Tell us what you’re shipping and we’ll put together a plan that fits.
Best for: Teams whose product is native mobile, or whose bottleneck is test authoring and maintenance rather than device access.
Not for: Teams that only want engineers hand-authoring web tests in CI, or that need physical-device, load, or API testing.
See How Pie Compares on Your App
Watch Pie discover and test your native mobile app in a 20-minute walkthrough.
Book a Walkthrough2. QA Wolf: The Fully Managed Service
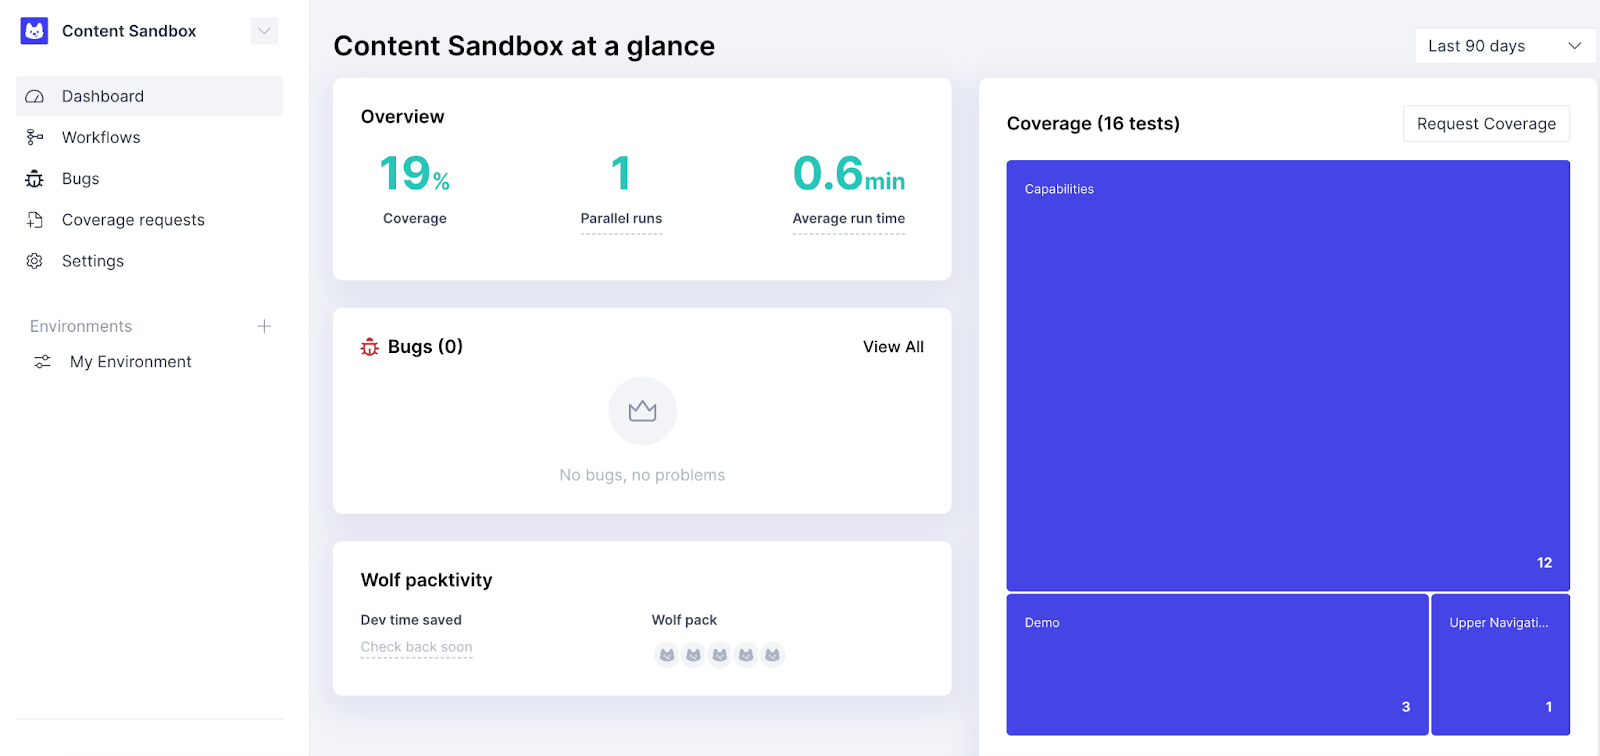
QA Wolf is for teams that want QA handled by someone else entirely. It is a managed service: a team of automation engineers, backed by AI, builds your tests in open-source Playwright, maintains them as your app changes, runs them on QA Wolf’s own infrastructure, and triages the failures so your team only sees real issues.
Rating (September 2026): 4.8/5 from 192 reviews on G2.
Where it wins:
- Zero authoring or maintenance load on your team; humans own the whole suite
- Real-device iOS and emulator-based Android coverage as a managed offering
- A human triages every failure, so your engineers never see the flaky ones
Where it falls short:
- Custom pricing that runs to a real budget line; Vendr puts the median buyer at $83,100 a year across 58 purchases
- You are buying an outcome, so day-to-day control sits with QA Wolf
Pricing: Coverage-as-a-Service with custom pricing. Vendr’s reported median is $83,100 a year.
Best for: Teams with little or no internal QA capacity that would rather buy the outcome than hire.
Not for: Teams that want to own and operate their own suite, or that need a low, predictable monthly license.
3. testRigor: Plain English for Non-Technical QA
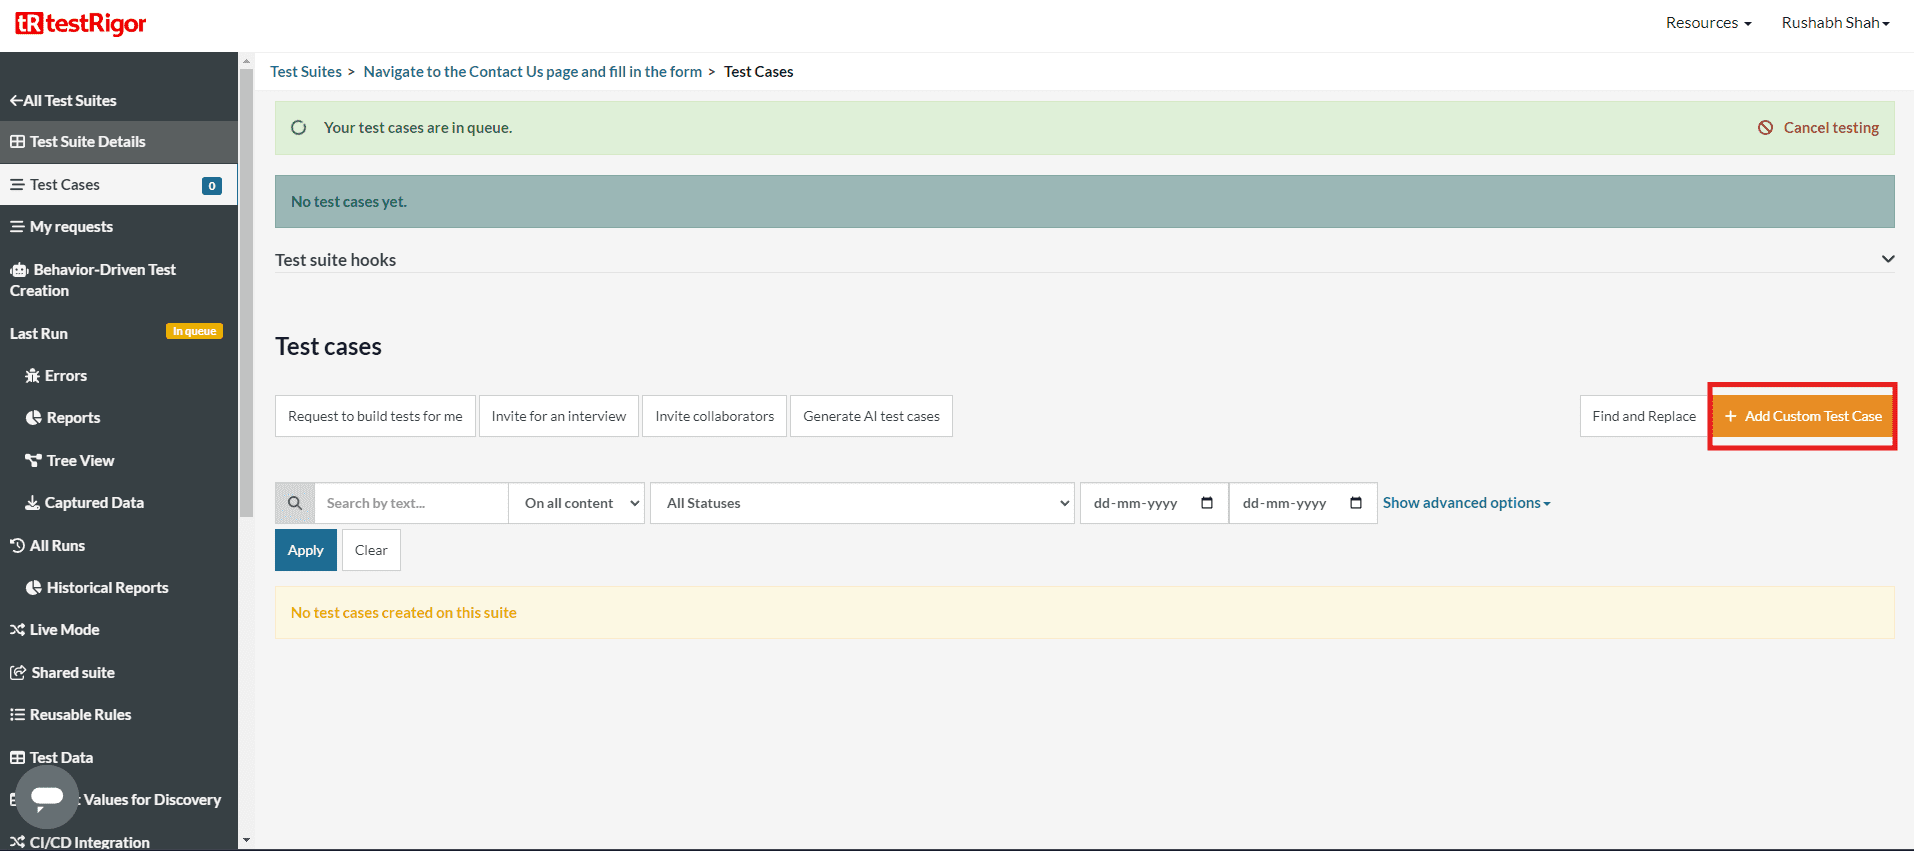
testRigor overlaps with Momentic on the plain-English idea but aims it at a different user. Where Momentic assumes engineers, testRigor is built so manual QA testers with no coding background can write tests as plain-English instructions, and its generative AI turns them into executable, self-healing tests across web, mobile, and Windows desktop.
Rating (September 2026): 4.7/5 from 41 reviews on G2 and 4.6/5 from 5 on Capterra.
Where it wins:
- Removes the coding requirement more aggressively than a developer-centric tool
- One plain-English model spans web, native mobile, and Windows desktop apps
- Self-healing keeps tests alive as the UI drifts
Where it falls short:
- Your team authors and owns the suite, with no hands-off option
- Very complex, deeply stateful flows can strain the plain-English model
- Desktop coverage stops at Windows
Pricing: Tiered subscription; contact testRigor for current plans.
Best for: QA orgs that are people-rich and engineer-poor, where removing the coding requirement is the whole game.
Not for: Teams that want coverage generated for them rather than authored by hand.
4. mabl: Low-Code for the Enterprise
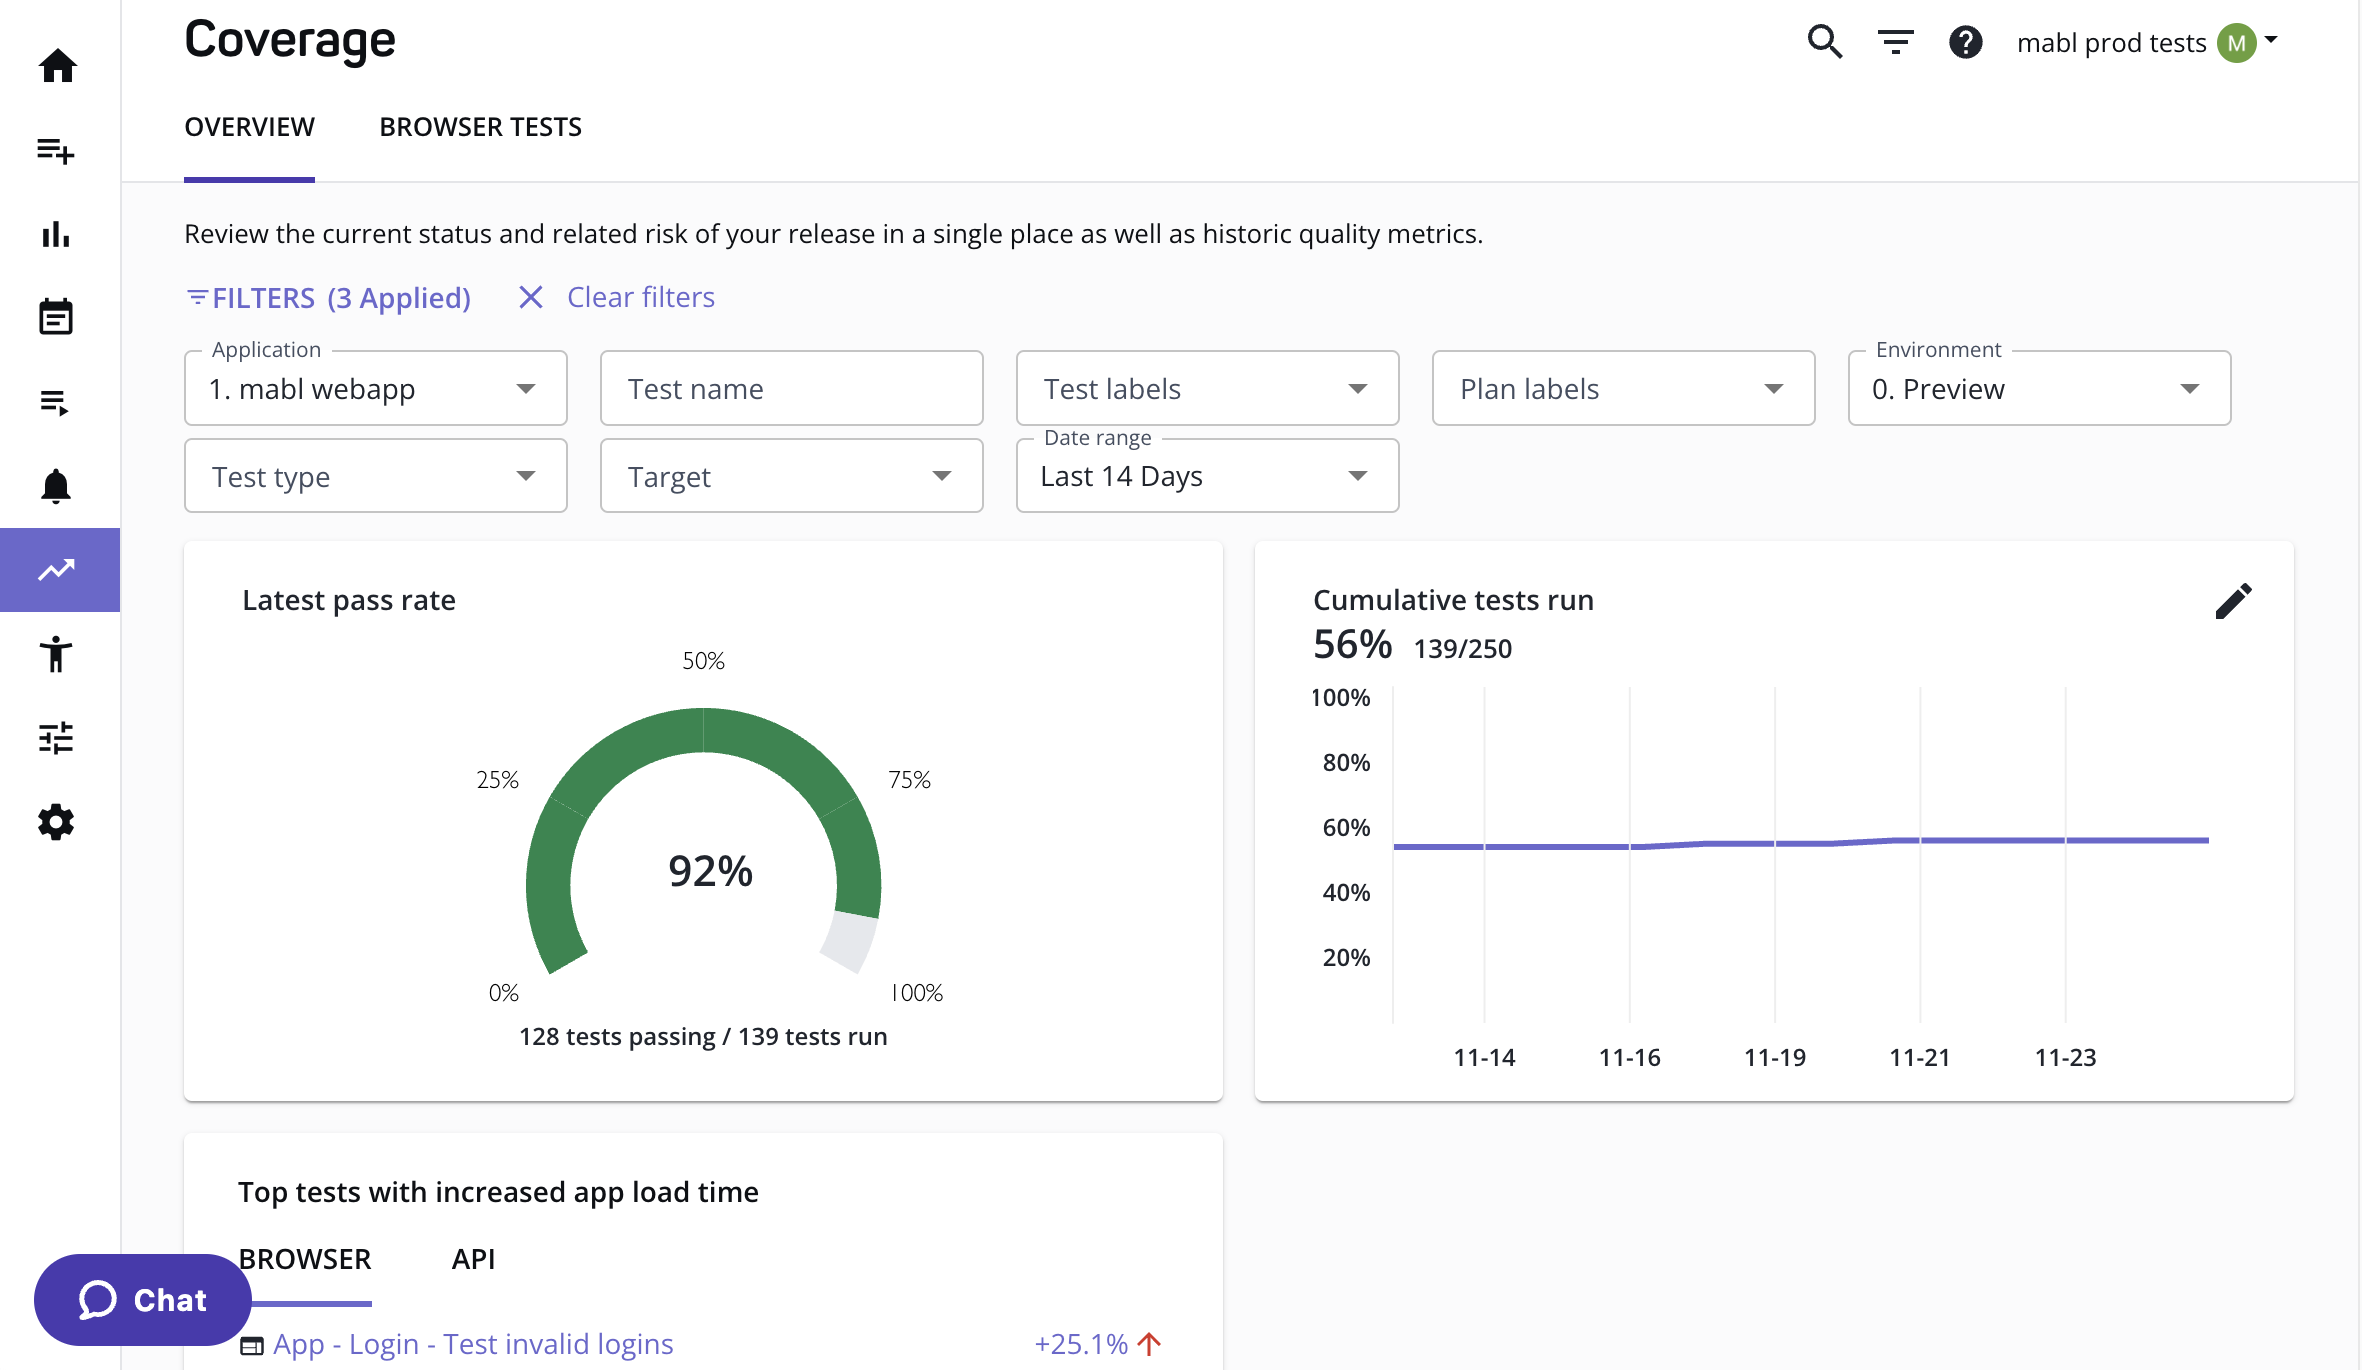
mabl is the enterprise play. It is a low-code platform that folds browser, API, native mobile, accessibility, and performance testing behind one GUI, with generative AI that drafts tests from a natural-language description or a pasted Jira ticket. What a large org is really buying, though, is the governance, analytics, and reporting that let it standardize testing across many teams at once.
Rating (September 2026): 4.4/5 from 40 reviews on G2.
Where it wins:
- Broad low-code coverage: web, API, native iOS and Android, accessibility, and performance in one platform
- Enterprise governance, audit trails, and centralized reporting
- Generative-AI test drafting from plain descriptions or tickets
Where it falls short:
- Native mobile runs on cloud simulators and emulators, so physical-hardware behavior is out of scope
- As with every tool here, your team still owns and maintains the suite
Pricing: Tiered subscription; contact mabl for current plans.
Best for: Enterprises that want one low-code platform with audit trails and centralized control over a developer-first authoring tool.
Not for: Small teams that want a lightweight tool, or teams bottlenecked on authoring effort, where governance is beside the point.
5. Applitools: When the Real Gap Is Visual
Applitools does a different job from Momentic, on purpose. Its Visual AI, branded Eyes, validates the rendered UI, text, images, and layout, catching the visual regressions that functional assertions miss. Eyes plugs into the framework you already run (Playwright, Cypress, Selenium, and others) and leaves your authoring approach alone. Applitools also ships Autonomous and a Codeless Recorder for generating end-to-end tests, but Eyes is the reason most teams reach for it.
Rating (September 2026): 4.3/5 from 90 reviews on G2; 4.6/5 on Capterra for Applitools Eyes from 30.
Where it wins:
- Visual AI catches layout, text, and rendering bugs functional tests miss
- Eyes layers onto 50+ frameworks with a single snippet, no rewrite
- Works across web and mobile via SDKs
Where it falls short:
- Eyes assumes you already have tests to attach it to; it is a validation layer on top of whatever authors your tests
- Deep visual coverage is a different job than end-to-end functional coverage, so it rarely stands alone
Pricing: Tiered subscription; contact Applitools for current plans.
Best for: Teams whose real pain is visual regression on top of tests they already run.
Not for: Teams that need their functional end-to-end coverage generated or authored in the first place.
6. Playwright: The Free, Code-Based Baseline
Playwright is the open-source baseline every paid tool is implicitly compared against. It is a free, code-based, cross-browser automation framework maintained by Microsoft, with no vendor lock-in and no per-test fees. For an engineering team that wants total control and zero license spend, it is the default, and recent Test Agents and an official MCP server bring optional AI assistance into the workflow.
Rating (September 2026): about 96,000 GitHub stars.
Where it wins:
- Free, open-source, and cross-browser, with no lock-in
- Maintained by Microsoft with a fast release cadence
- Test Agents (planner, generator, healer) and an MCP server add AI assistance
Where it falls short:
- You write every test and every selector, and maintain them when the UI changes; the healer agent fixes tests during authoring and CI runs, not as runtime self-healing
- Mobile means browser and emulation, with no native iOS or Android app testing
Pricing: Free and open-source (Apache-2.0).
Best for: Engineering teams whose constraint is budget and control, with the engineers to absorb the upkeep.
Not for: Teams that adopted Momentic specifically to stop writing and maintaining tests, or that need native mobile coverage.
Which Alternative Verifies AI-Generated Code?
The newest reason teams go shopping never made the old checklist. Your engineers now ship code they did not type, faster than anyone can write a test for it, and that code needs more scrutiny than the code your team typed. Uplevel’s analysis of nearly 800 developers found 41% more bugs with an AI assistant and no gain in throughput, and Stack Overflow’s 2025 survey put code that is “almost right, but not quite” at the top of developers’ AI frustrations, the bug that survives a glance.
The question that sorts them is what a tool checks a feature against, and there are two answers.
Codebase-First: Tests Derived From the Code
Autonoma explores the codebase to draft a test plan, and Momentic’s diff-reading agent works from the same raw material, so coverage lands the moment code does. The catch sits in the design. Derive the assertion from the implementation and a bug the model wrote gets encoded as expected behavior, so you have proved the mistake is reproducible.
Behavior-First: Tests Derived From the Running App
TestSprite and Shiplight work this way on web and API. Pie does it on native iOS and Android as well as web, judging what happens on screen against intended behavior, which none of the others in this group can do yet.
Which One Catches What
Do not read that as behavior-first winning. Each approach has a blind spot the other covers.
- Codebase-first catches: A privilege check that returns the wrong row, a webhook that fires twice, anything that never shows up on screen and so never looks wrong.
- Behavior-first catches: The bug the model wrote and then tested for, because verifying AI-generated code against what a user sees does not inherit the code’s assumptions.
Teams shipping a lot of machine-written code usually run both, with unit and contract tests underneath. If you only get one, pick by where your last three painful bugs lived.
Match Your Constraint to the Right Tool
Choosing a Momentic alternative comes down to one question, answered honestly before any demo. What constraint sent you looking? Feature counts and AI labels will not tell you. The specific cost your team is paying will. Work down the scenarios below and stop at the first that matches.
Choose Pie if…
You want broad coverage without anyone on your team authoring or maintaining tests, and native iOS or Android is a first-class surface rather than a line item you meter. Pie discovers the app, generates and self-heals the suite, and drafts the fix through Pie Loop when a test catches a regression. Ownership is the constraint it removes. If you want to write specific tests yourself, buy an authoring tool.
Choose QA Wolf if…
You want QA fully outsourced to a human team and have the budget for it. QA Wolf builds, maintains, runs, and triages your suite as a managed service, so the outcome arrives without your team operating anything. If the shortlist is down to those two, the QA Wolf versus Momentic comparison walks the trade in full.
Choose testRigor if…
Your QA team is manual testers with no automation engineers behind them. testRigor’s plain-English authoring lets them create and maintain tests without code, across web, mobile, and Windows desktop. Pick it when the coding requirement is the only thing standing between your testers and automation.
Choose mabl, Applitools, or Playwright if…
You are an enterprise wanting one low-code platform with governance (mabl), your real gap is visual regression on top of tests you already have (Applitools Eyes), or your constraint is budget and control and you have engineers to maintain a code-based suite (Playwright).
None of these tools is universally best, and several pair well together. The teams that choose well skip the question of which AI testing tool wins and ask which problem is costing them the most, then pick the tool built to remove that cost. Answer that first, and the shortlist of six becomes a shortlist of one.
Where This Leaves You
Momentic is a strong tool that closed two of its own gaps this summer, and if your engineers want to author plain-English tests and own them in CI, staying put is a fine answer. Check the date on any comparison telling you otherwise, including the ones that still say it cannot test mobile.
Teams leave for a reason no release fixes. Somebody has to hold the suite. A QA org without automation engineers has no one to hand it to. A mobile-first team watches the meter run on the screens it most needs covered. And some teams simply do not want a test suite as a possession at all.
The last group is who we built Pie for. It finds the flows on its own, writes and maintains the coverage, verifies what it finds, and drafts the fix when something breaks. You ship. We handle the testing.
Stop Maintaining Tests. Start Shipping.
See Pie discover, generate, and self-heal tests across native iOS and Android in a 20-minute demo.
Book a DemoFrequently Asked Questions
There is no single best one, because the right pick depends on what you are trying to stop paying for. Pie suits teams that want native mobile coverage without anyone authoring or maintaining tests. QA Wolf suits teams who want the whole suite handed to a managed human team. testRigor suits QA orgs staffed with manual testers rather than automation engineers.
The wrong move is buying a tool that does what Momentic already does well, which since its June 2026 release includes native mobile and tests proposed from pull-request diffs.
Yes, and it is worth checking the date on anything telling you otherwise. Momentic is a well-funded AI end-to-end platform used by teams at Notion, Quora and Webflow, and it raised a $15M Series A led by Standard Capital in November 2025. Engineers describe tests in plain English, Momentic stores them as specs in the repo, and they run in CI.
A June 2026 release added hosted iOS and Android devices and an agent that proposes tests from pull-request diffs, which retired two of the objections older comparison posts still repeat.
It depends where your bugs actually live. Tools that read your repository, such as Autonoma and Momentic's own diff-reading agent, cover a new route the moment the code lands, though a test derived from the implementation can encode a mistake the model made as expected behavior.
Tools that drive the running product check what a user would see instead. TestSprite and Shiplight work this way and are web and API only today. Pie does it across web and native mobile. Neither approach is strictly safer, so teams shipping heavy AI code often run both.
Pie is the strongest pick when you want native mobile coverage without authoring the tests. It reads the rendered screen with a vision model rather than accessibility trees or selectors, and covers native iOS and Android from one autonomous run on simulators and emulators. QA Wolf also covers mobile as a managed service, using real devices for iOS.
Momentic added hosted iOS and Android devices in June 2026 and bills them per device minute, so reaching mobile is no longer the differentiator. Who maintains the mobile suite still is.
Yes. Playwright is the leading free, open-source option. It is code-based, cross-browser, maintained by Microsoft, and carries no vendor lock-in or per-test fees, with roughly 96,000 GitHub stars behind it.
The trade-off is that you write and maintain every test and every selector yourself, which is the exact cost the AI tools exist to remove. Open source is the right call when your constraint is budget and control rather than engineering time.
Momentic publishes a free tier and a pay-as-you-go plan at $125 a month with Enterprise quoted on request, and it bills hosted mobile devices separately by the minute. Managed services price higher, and Vendr puts QA Wolf's median buyer at $83,100 a year.
testRigor and mabl publish tiered subscriptions, and Playwright is free. Model the engineering time spent maintaining tests alongside the license, because that is usually the larger number.
Both are common. Plenty of teams keep an authoring tool for engineer-written critical paths and add a second tool for the gap it does not cover, such as autonomous native-mobile coverage from Pie or deep visual validation from Applitools Eyes.
Replacement makes sense when one alternative covers your whole surface better than your current setup. Because these tools operate at different layers, running two is a reasonable answer rather than an admission that the first one failed.
They sit at different layers. Momentic is a tool your engineers author tests in, stored as plain-English specs in your repo and run in CI, and its agent can now propose tests from a pull-request diff. Either way a person reviews the test and your team owns the suite afterwards.
Pie is an autonomous platform that explores the app, generates the tests, runs them and self-heals them, so coverage is the platform's job rather than an authoring task. Both reach native iOS and Android, and Pie reads the rendered screen with a vision model.
13 years building mobile infrastructure at Square, Facebook, and Instacart. Now building the QA platform he wished existed the whole time. LinkedIn →